Transcribe audio and video
Turn speech into timed subtitles. Choose a local model and language; the app tests your device before the first run.
Transcribe, translate, and style subtitles—all on your device.
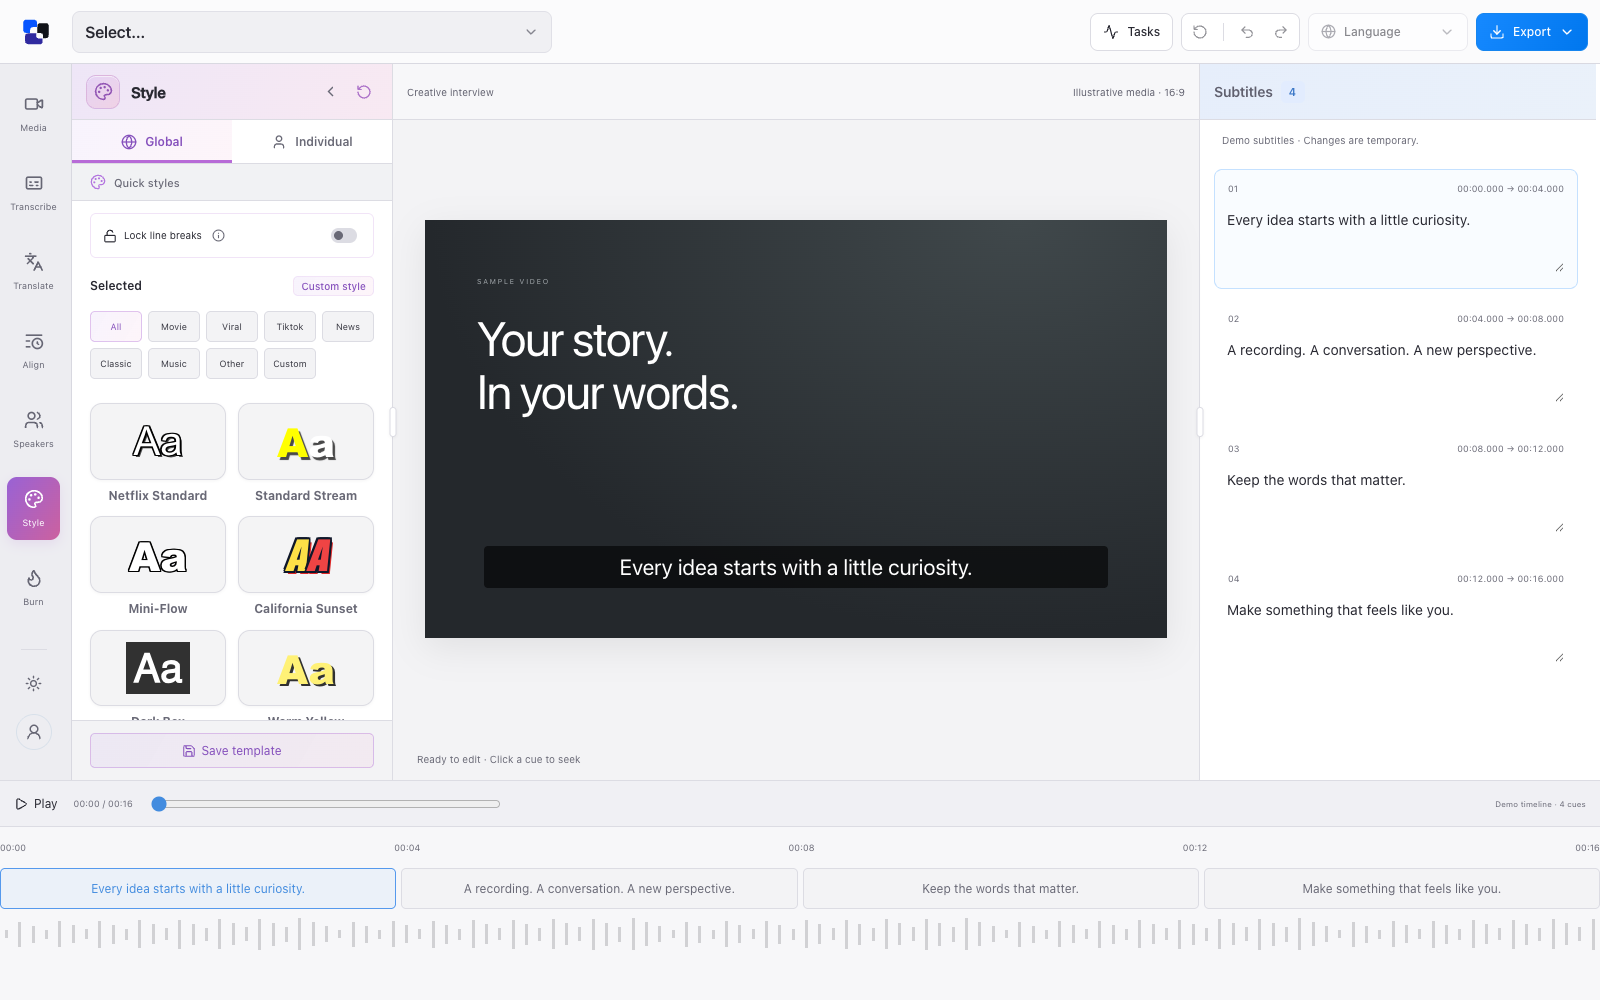
Transcribe audio or video into timed subtitles, then edit, translate, and style them alongside your media. Export SRT, VTT, or ASS files, or render a video with captions built in.
Turn speech into timed subtitles. Choose a local model and language; the app tests your device before the first run.
Play your media while editing subtitle text and timing. Fine-tune word boundaries where supported, with undo and redo.
Translate a full track or selected subtitles. Keep each language in its own track for review and editing.
Refine timing with alignment models and add speaker labels. Review the results before applying them.
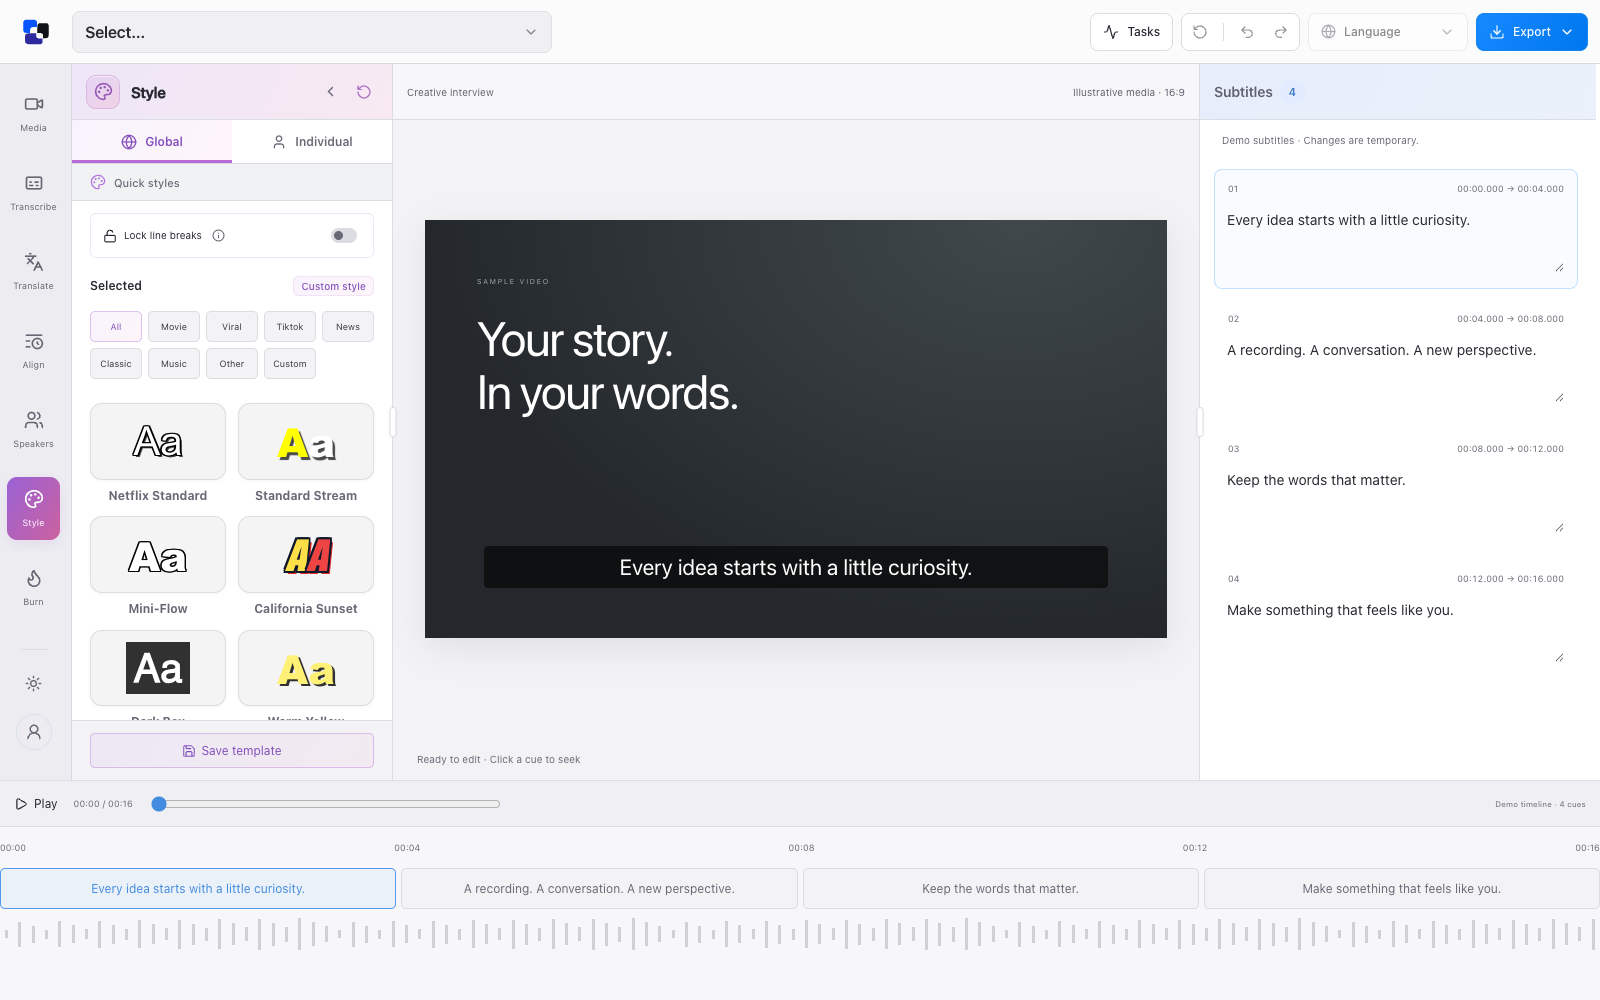
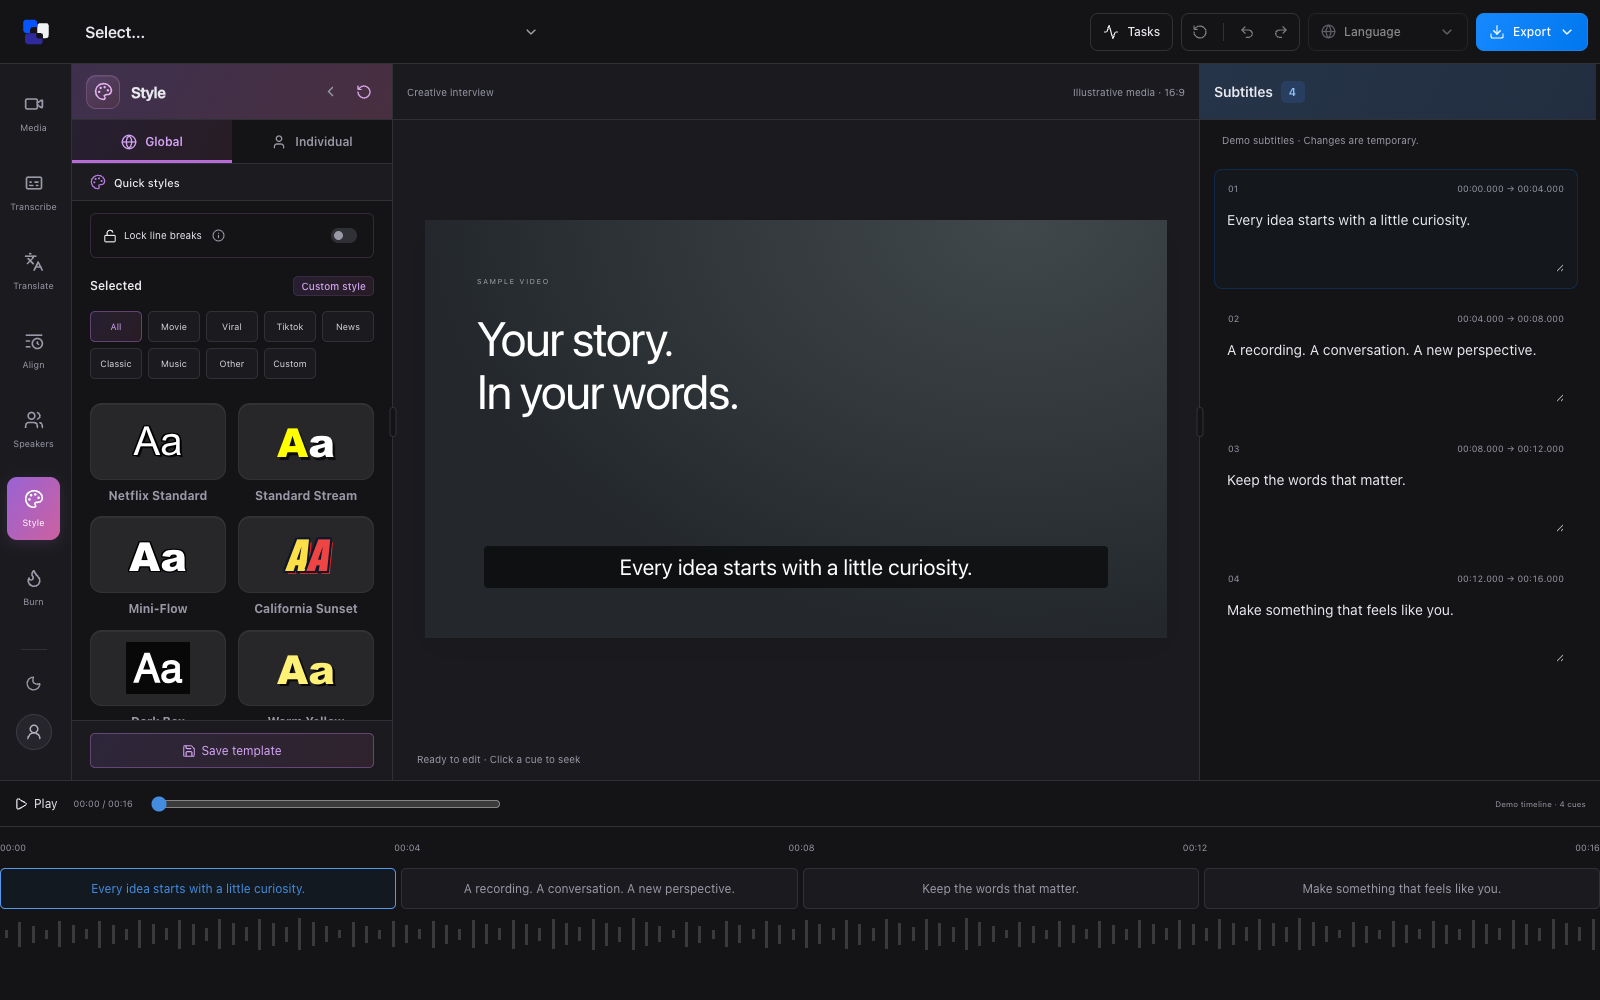
Choose a preset or customize fonts, colors, and placement. Preview changes across a track or on one subtitle.
Control subtitle length, word count, and line breaks. Split at pauses and sentences to keep captions readable.
Save SRT, VTT, or styled ASS files. Export transcripts or JSON, including word and speaker details when available.
Save a video with styled captions built in. Your original media stays separate.
Reopen your media, tracks, styles, and saved runs. Projects stay in this browser, with local storage controls.
Create a project and choose an audio or video file.
Choose a model and language, then generate subtitles. The app downloads the model and tests your device on first use.
Check the text and timing, add translations or styling, then download subtitles or a captioned video.
We’ll email you when Local AI SRT / Subtitles Generator is ready.
 Qwen / Alibaba Cloud
Align a matching English transcript to audio locally in the browser. Returns complete word boundaries; Q4 WebGPU recommended, WASM CPU fallback measured independently.
Qwen / Alibaba CloudAlign an existing transcript to mono audio and estimate word/character start and end times using the official non-autoregressive 5000-class timestamp head. Does not transcribe unknown speech.
 NVIDIA
Align a matching transcript to its recording with the auxiliary CTC checkpoint distributed with NVIDIA Canary 2.
 Helsinki-NLP / University of Helsinki
Translate English text into Spanish and return the translated text. This worker supports only English-to-Spanish translation, not automatic language detection or other language pairs.
 Google
Translate text or text visible in still images locally. Supply source and target language codes; review OCR, names, numbers and omissions.
 Tencent Hunyuan
Translate short text in four verified directions: English→Spanish, Spanish→English, English→French and Chinese→English. Tencent’s community license applies; review every translation.
Tencent HunyuanTranslate short multilingual text locally with the original HY-MT1.5 1.8B checkpoint and official source-aware translation prompt.
Tencent HunyuanTranslate text locally with Tencent Hy-MT2 1.8B using explicit language selections and the official translation prompt.
 Tether AI Research
Local English to French translation using the original FP32 EuroNano Base checkpoint.
Qwen / Alibaba CloudRun local text questions, still-image questions using Qwen3.5 4B Desktop. Answers can hallucinate or miss visual details.
 Liquid AI
Ask questions, draft short text, and experiment with multilingual conversations using a compact chat model. Returns an assistant reply; complex reasoning and factual answers need review.
 Swiss AI Initiative (ETH Zurich / EPFL)
Ask questions, draft short text, or continue a conversation with a compact multilingual chat model. Returns an assistant reply; answers can be inaccurate and should be checked.
Qwen / Alibaba CloudChat with text or images locally using Qwen3.5.
GoogleChat with text, images or WAV audio using the complete Gemma 4 E2B and E4B checkpoints on verified configurations.
NVIDIATranscribe speech with punctuation and approximate word-level timestamps. Native multilingual FastConformer/TDT decoding retains complete token timings and durations.
 Microsoft
Transcribe authorized WAV files locally with the 1.5B streaming checkpoint. Native speaker-prefixed text and complete chunk outputs arrive progressively; hotword context is optional.
 OpenAI
Transcribe WAV audio locally with word-level timestamps in seconds.
NVIDIATranscribe speech locally in your browser with NVIDIA Parakeet TDT 0.6B v3. Returns punctuation, word and token timestamps, confidence scores and the complete native result.
 Meta
English speech recognition with word-level CTC emission timestamps. Returns transcript, complete word timings and model confidence; no speaker labels or translation.
OpenAIMultilingual transcription, English translation, and optional timestamps.
OpenAIMultilingual transcription, English translation, and optional timestamps.
NVIDIATranscribe local audio progressively with NVIDIA’s multilingual RNNT model. Returns complete text, approximate word-level timestamps and the native recognition result.
 pyannote
Estimate who spoke when locally using pyannote Community-1. Returns regular and exclusive speaker-turn timelines with anonymous speaker labels, not names or transcripts.
 k2-fsa / pyannote / 3D-Speaker
Identify anonymous speaker turns locally with pyannote segmentation and3D-Speaker embeddings. Returns a complete speaker timeline; WASM CPU only.
NVIDIAIdentify up to four speaker channels in speech recordings with incremental timed segments.
NVIDIAEstimate anonymous speaker turns from complete WAV recordings with the native eight-channel Nemotron3 diarization model.